Production data is the best test data — and the one you can't use
PHI, PII, and sensitive customer records are locked away from sandboxes, QA environments, demos, and analytics pipelines. Classic generators optimize for column-level realism and break the relationships that make data useful for testing.
Broken relationships kill tests
Classic generators shuffle columns independently — joins fail, automations error, and data-dependent workflows produce false negatives that aren't bugs.
Compliance needs evidence, not promises
A statement that data is "anonymized" isn't enough. Reviewers need reproducible PASS / WARN / FAIL metrics they can validate and retain.
Sandbox refreshes reset everything
Every refresh means another compliance review, another manual scrub, another delay before QA can safely run. There's no durable, repeatable path.
Relation-preserving synthesis, end to end
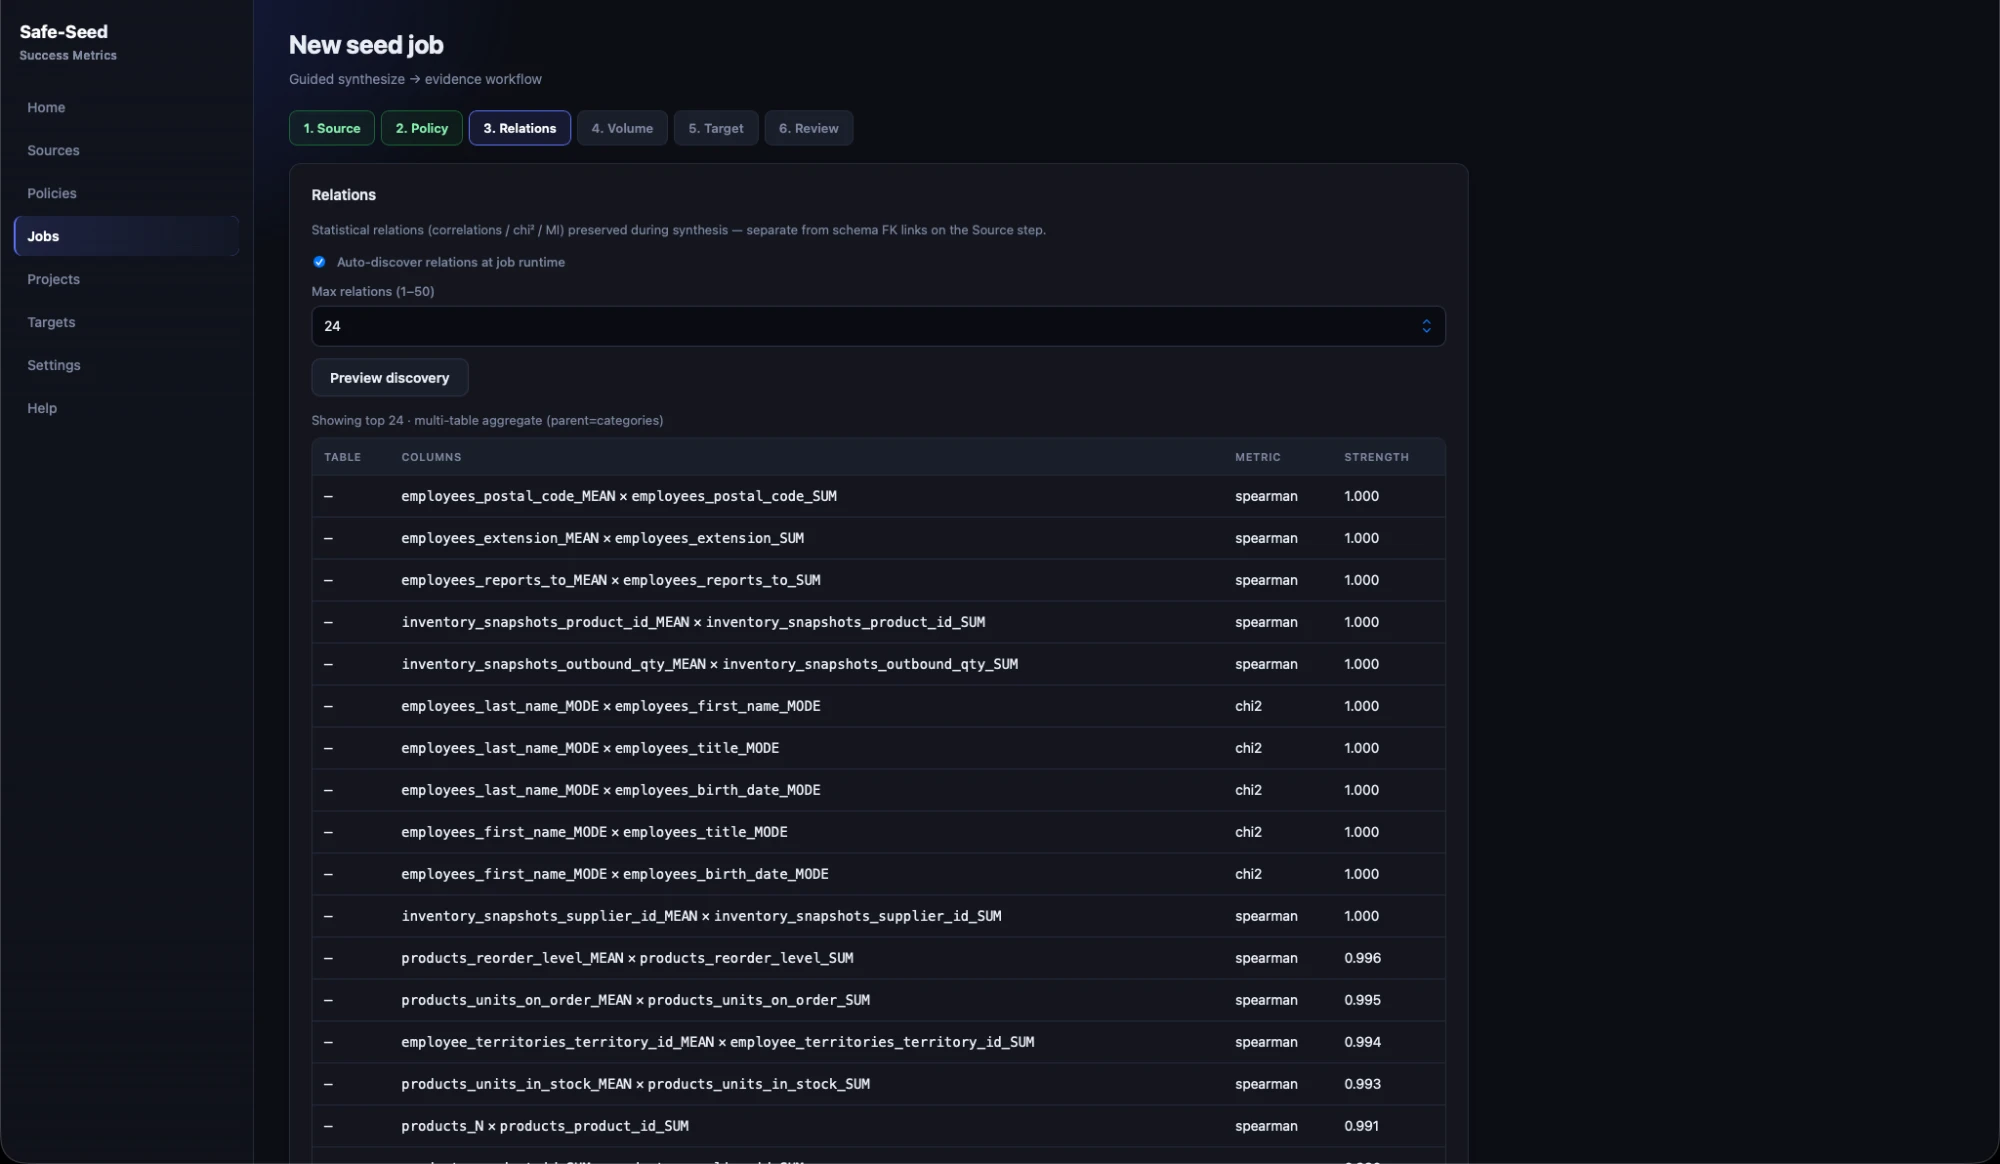
Every Safe Seed run preserves the statistical and relational structure of your source data — so synthetic outputs behave like production in tests, demos, and analytics pipelines.
Mask without breaking joins
PII columns masked while preserving stable, usable join keys. Per-run privacy metrics for reviewers and legal — with role separation so inspectors don't mutate sources.
Full relational reconstruction
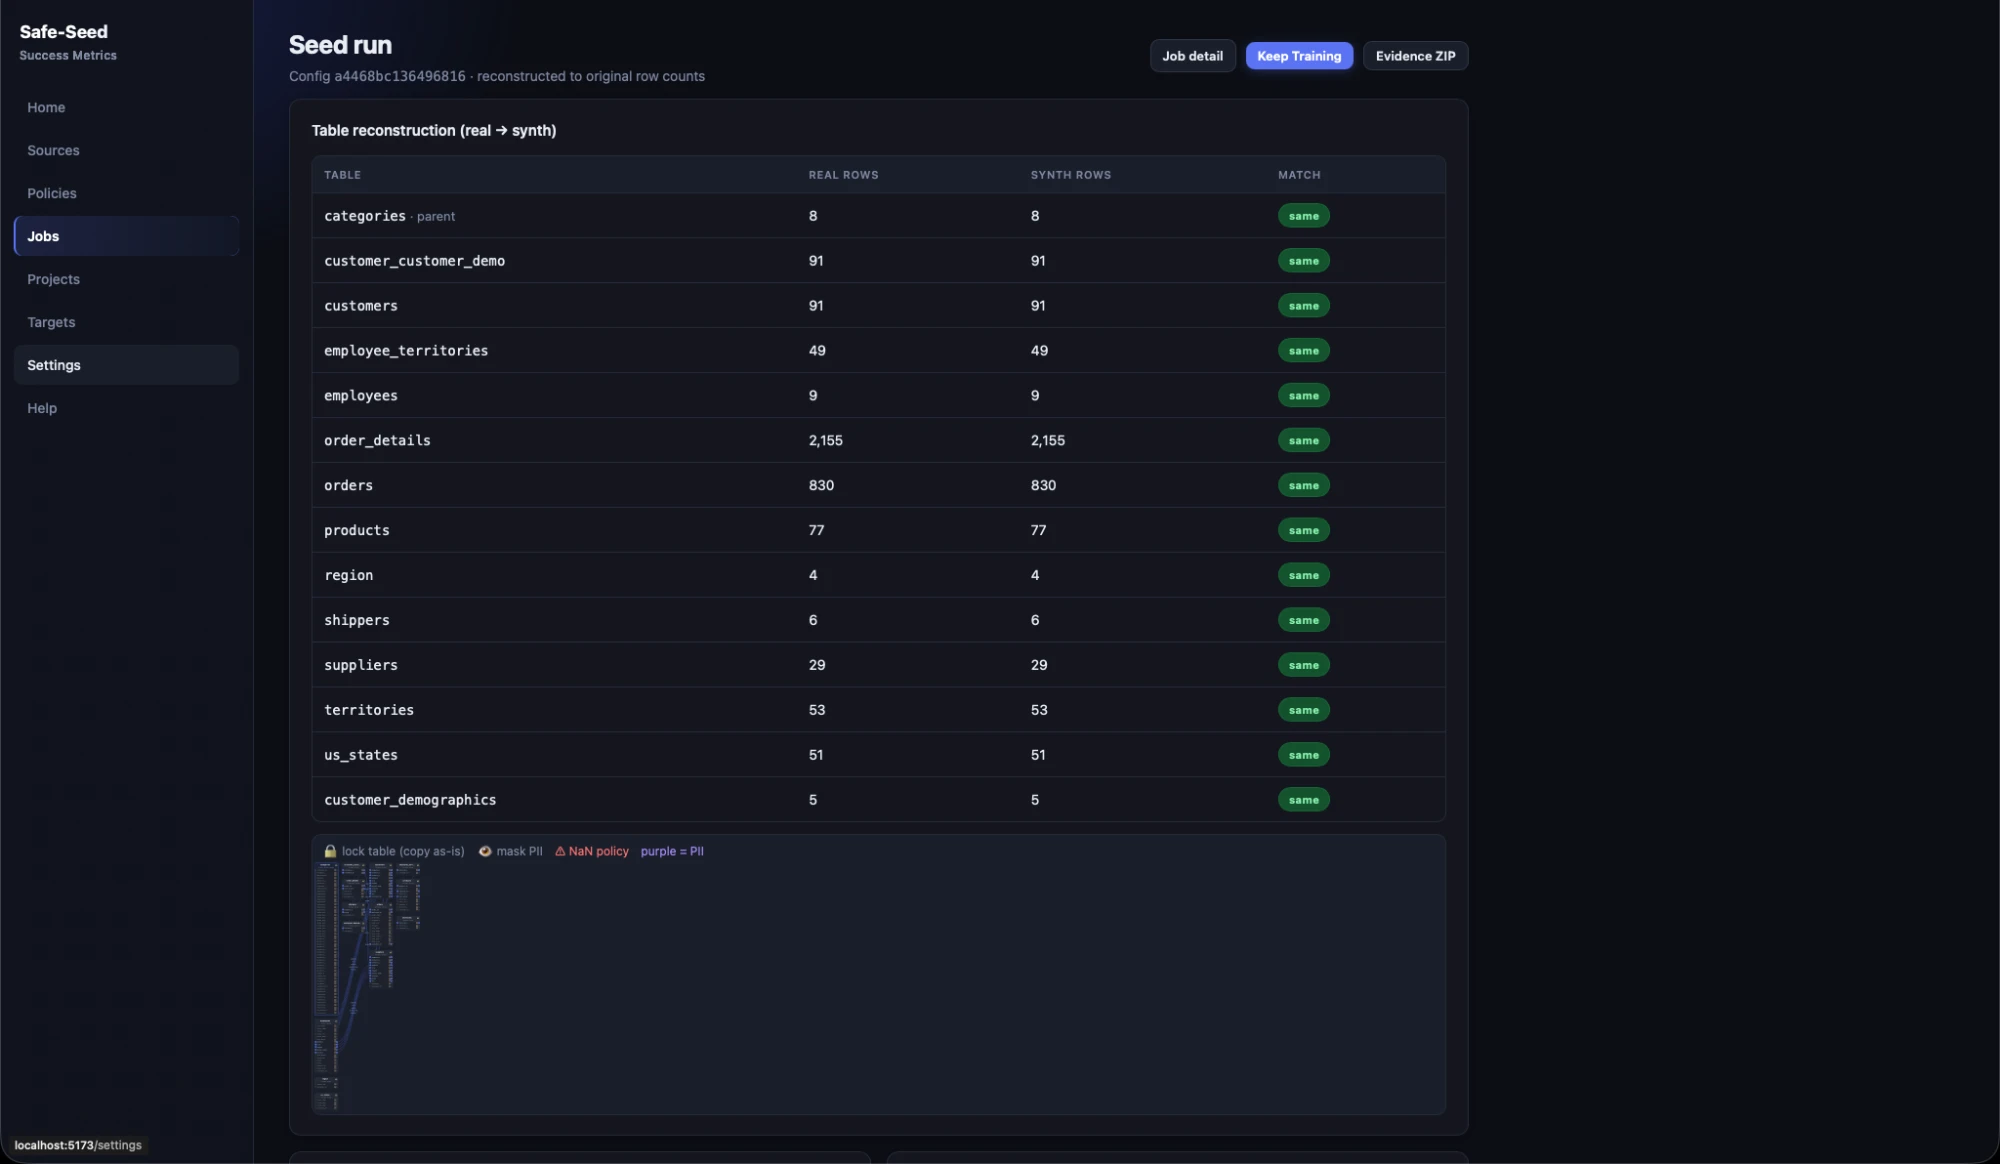
Synthesize parents first, reconstruct children with referential integrity. Locked tables pass through unchanged for mixed real/synthetic environments where some tables should stay untouched.
Measure every run
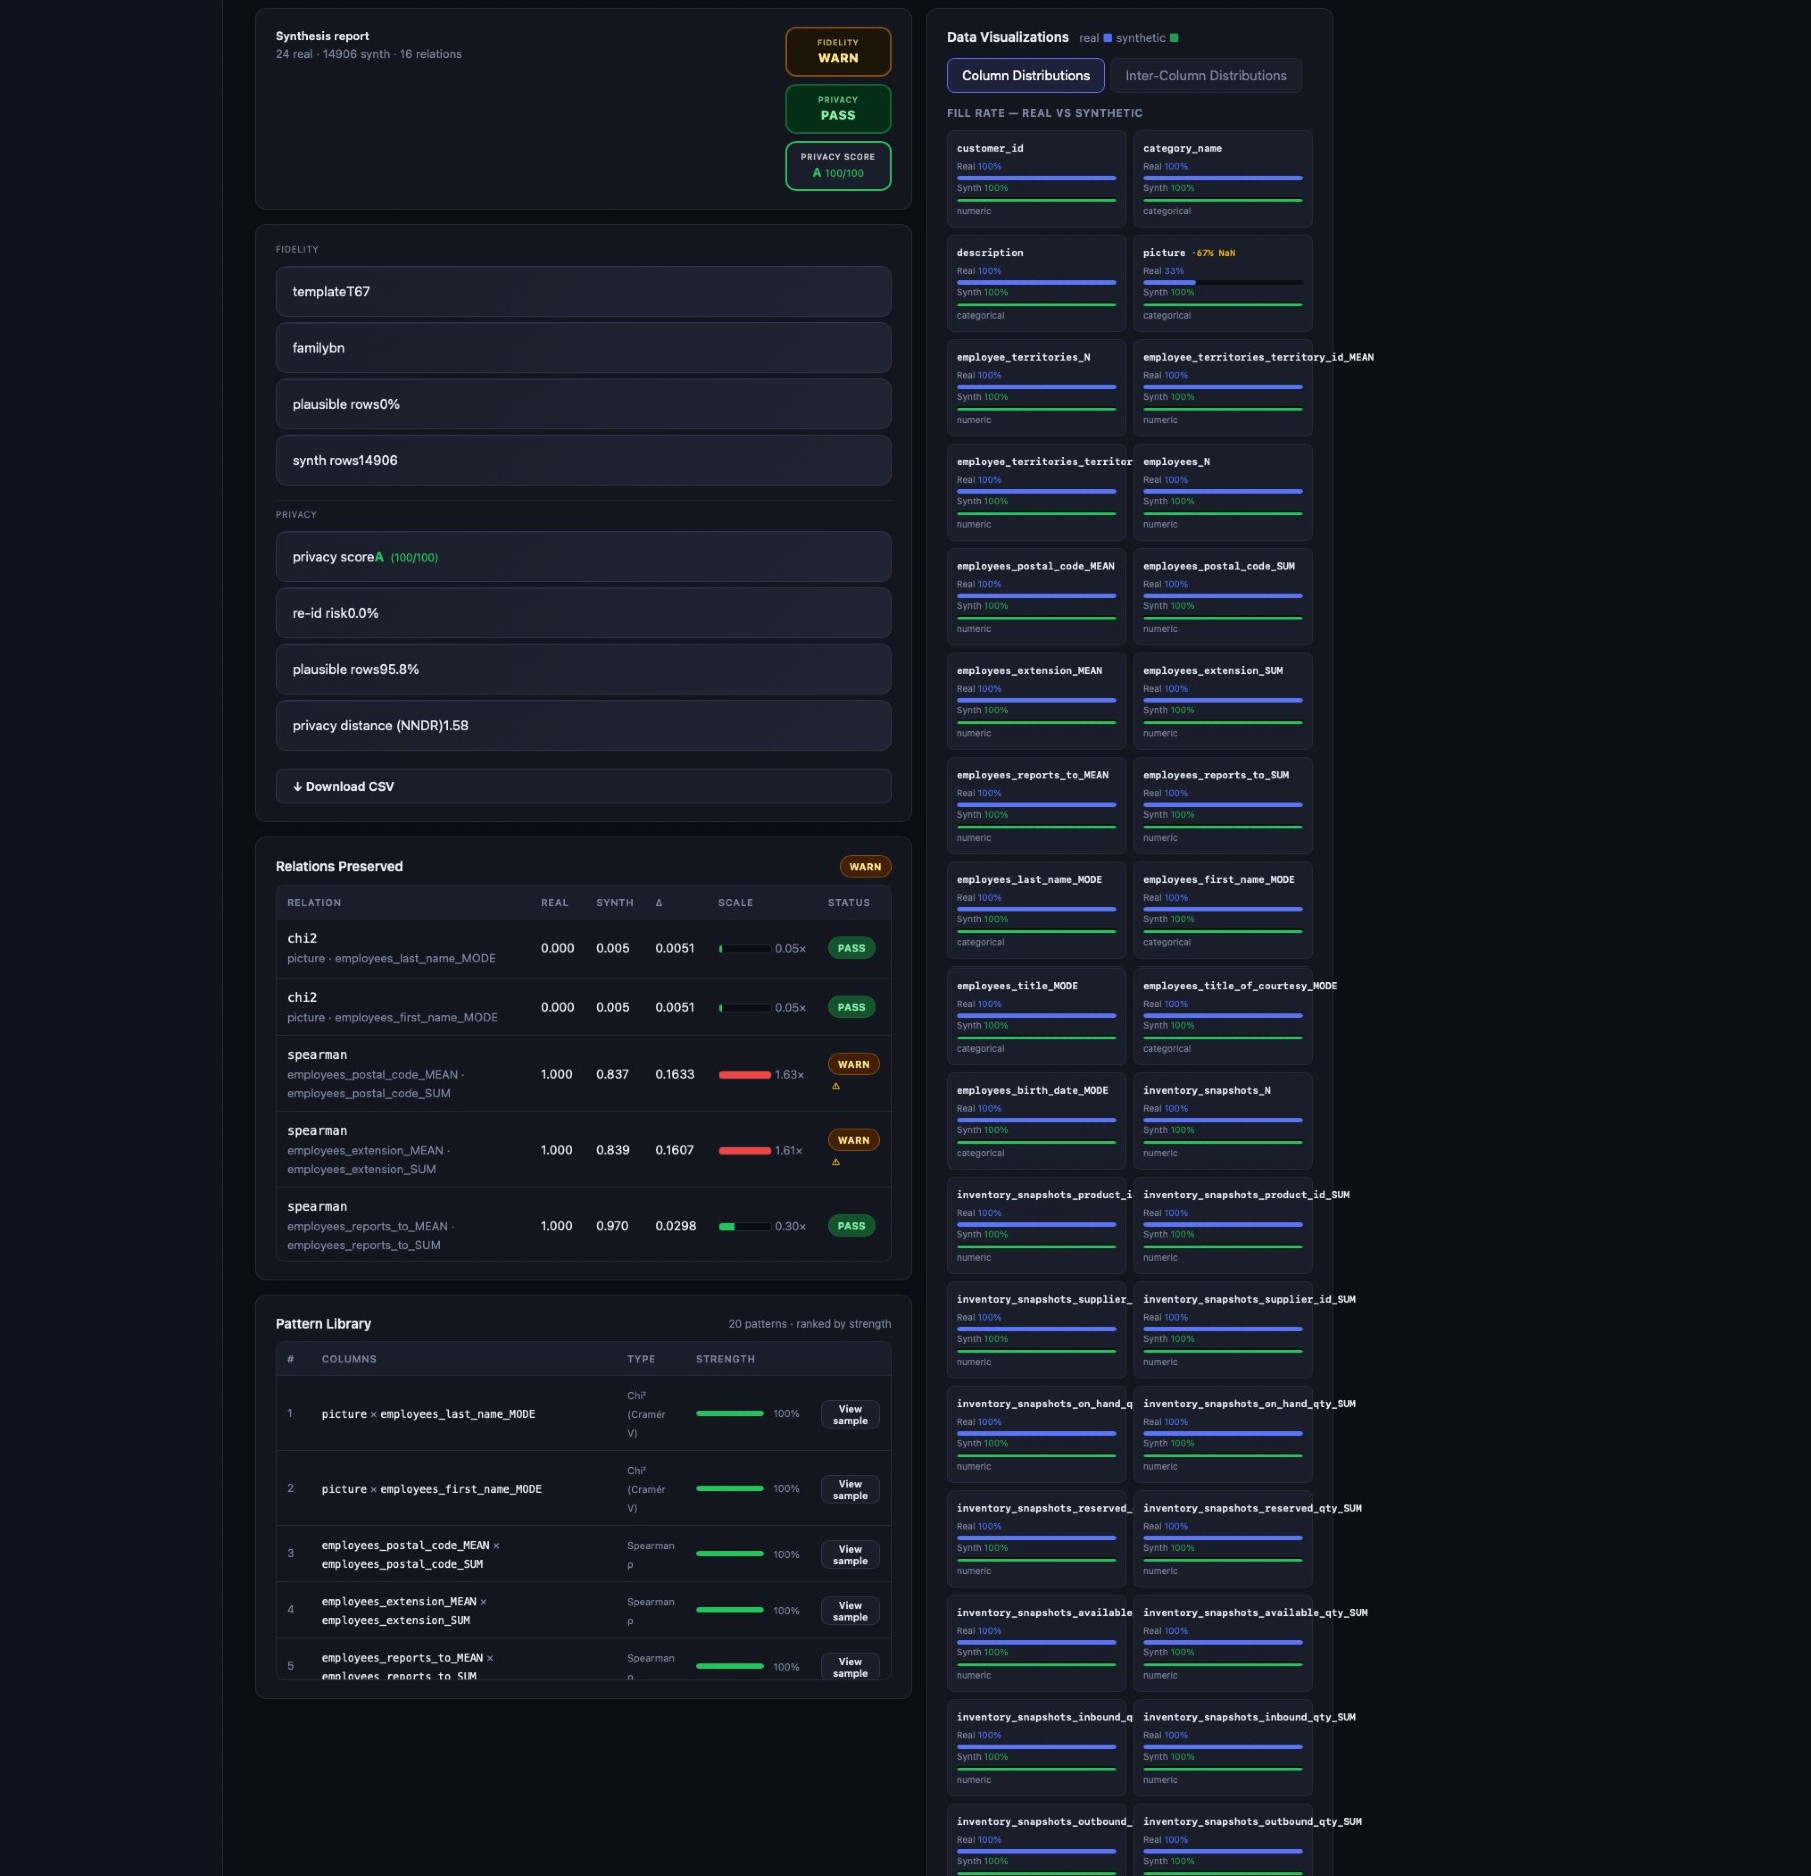
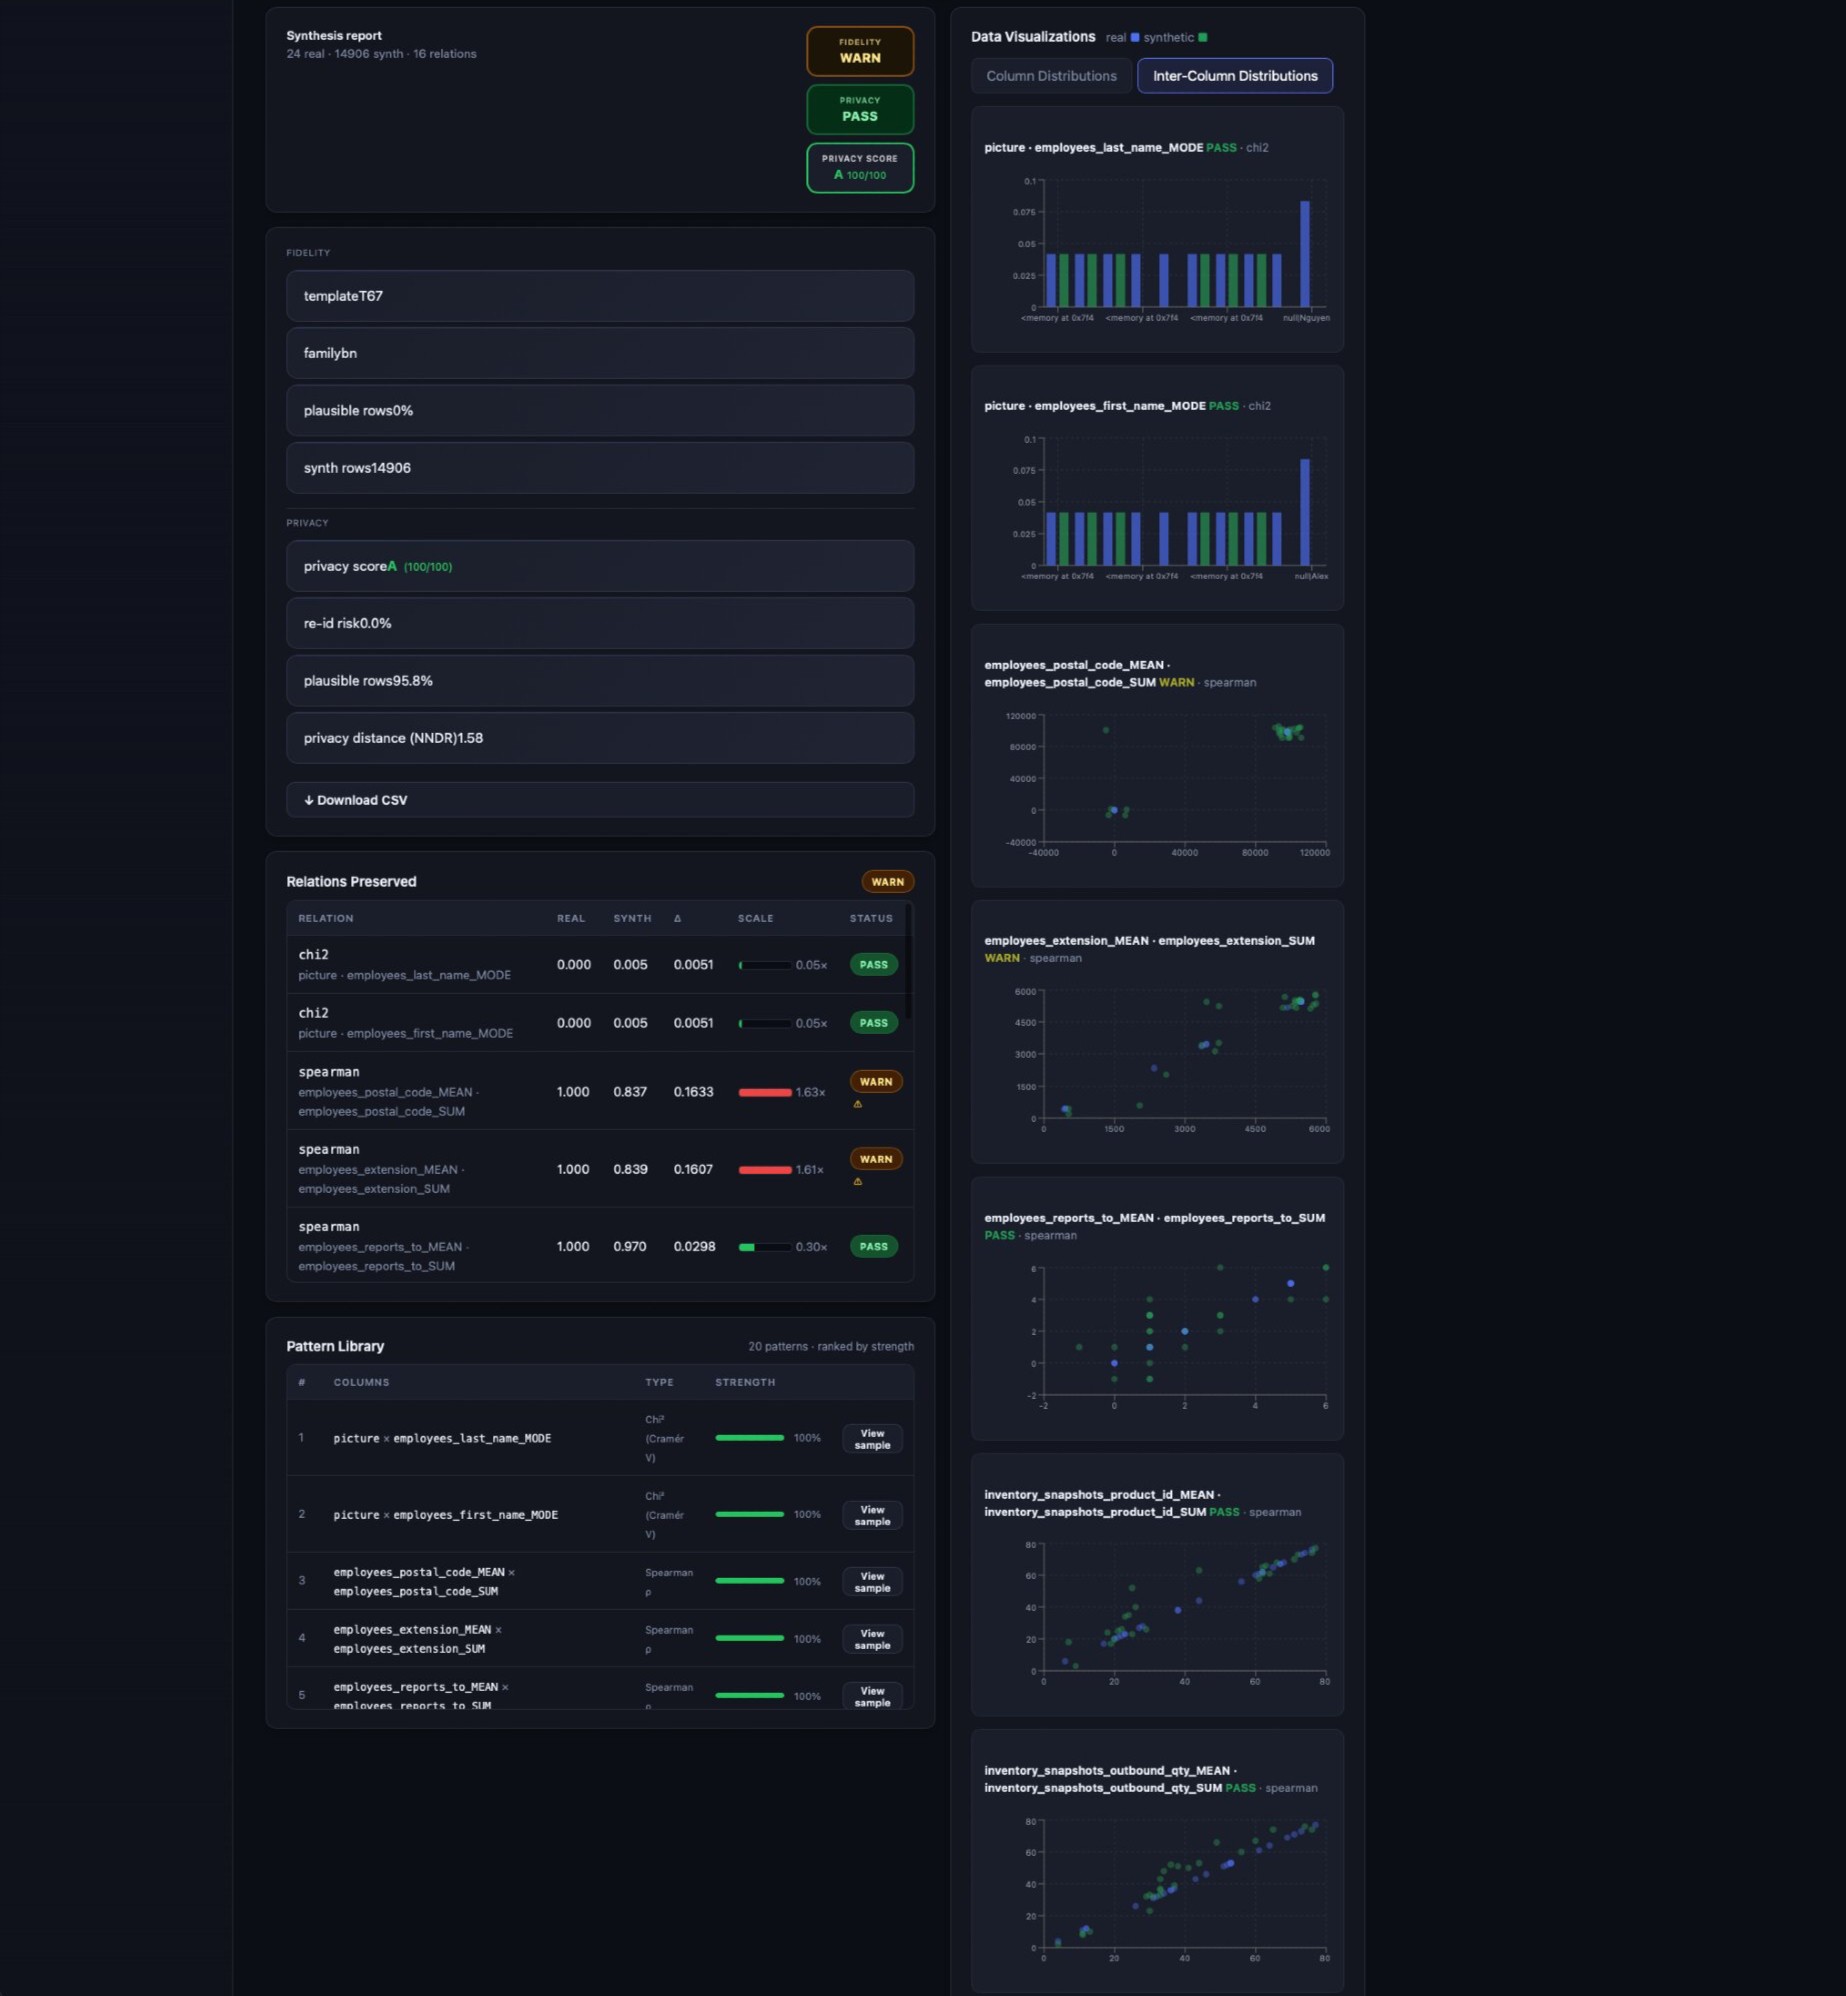
Per-relation real-vs-synthetic deltas included in every report. Adaptive Keep Training warm-starts from a completed run to deepen fidelity — no full re-run required.
Null patterns preserved
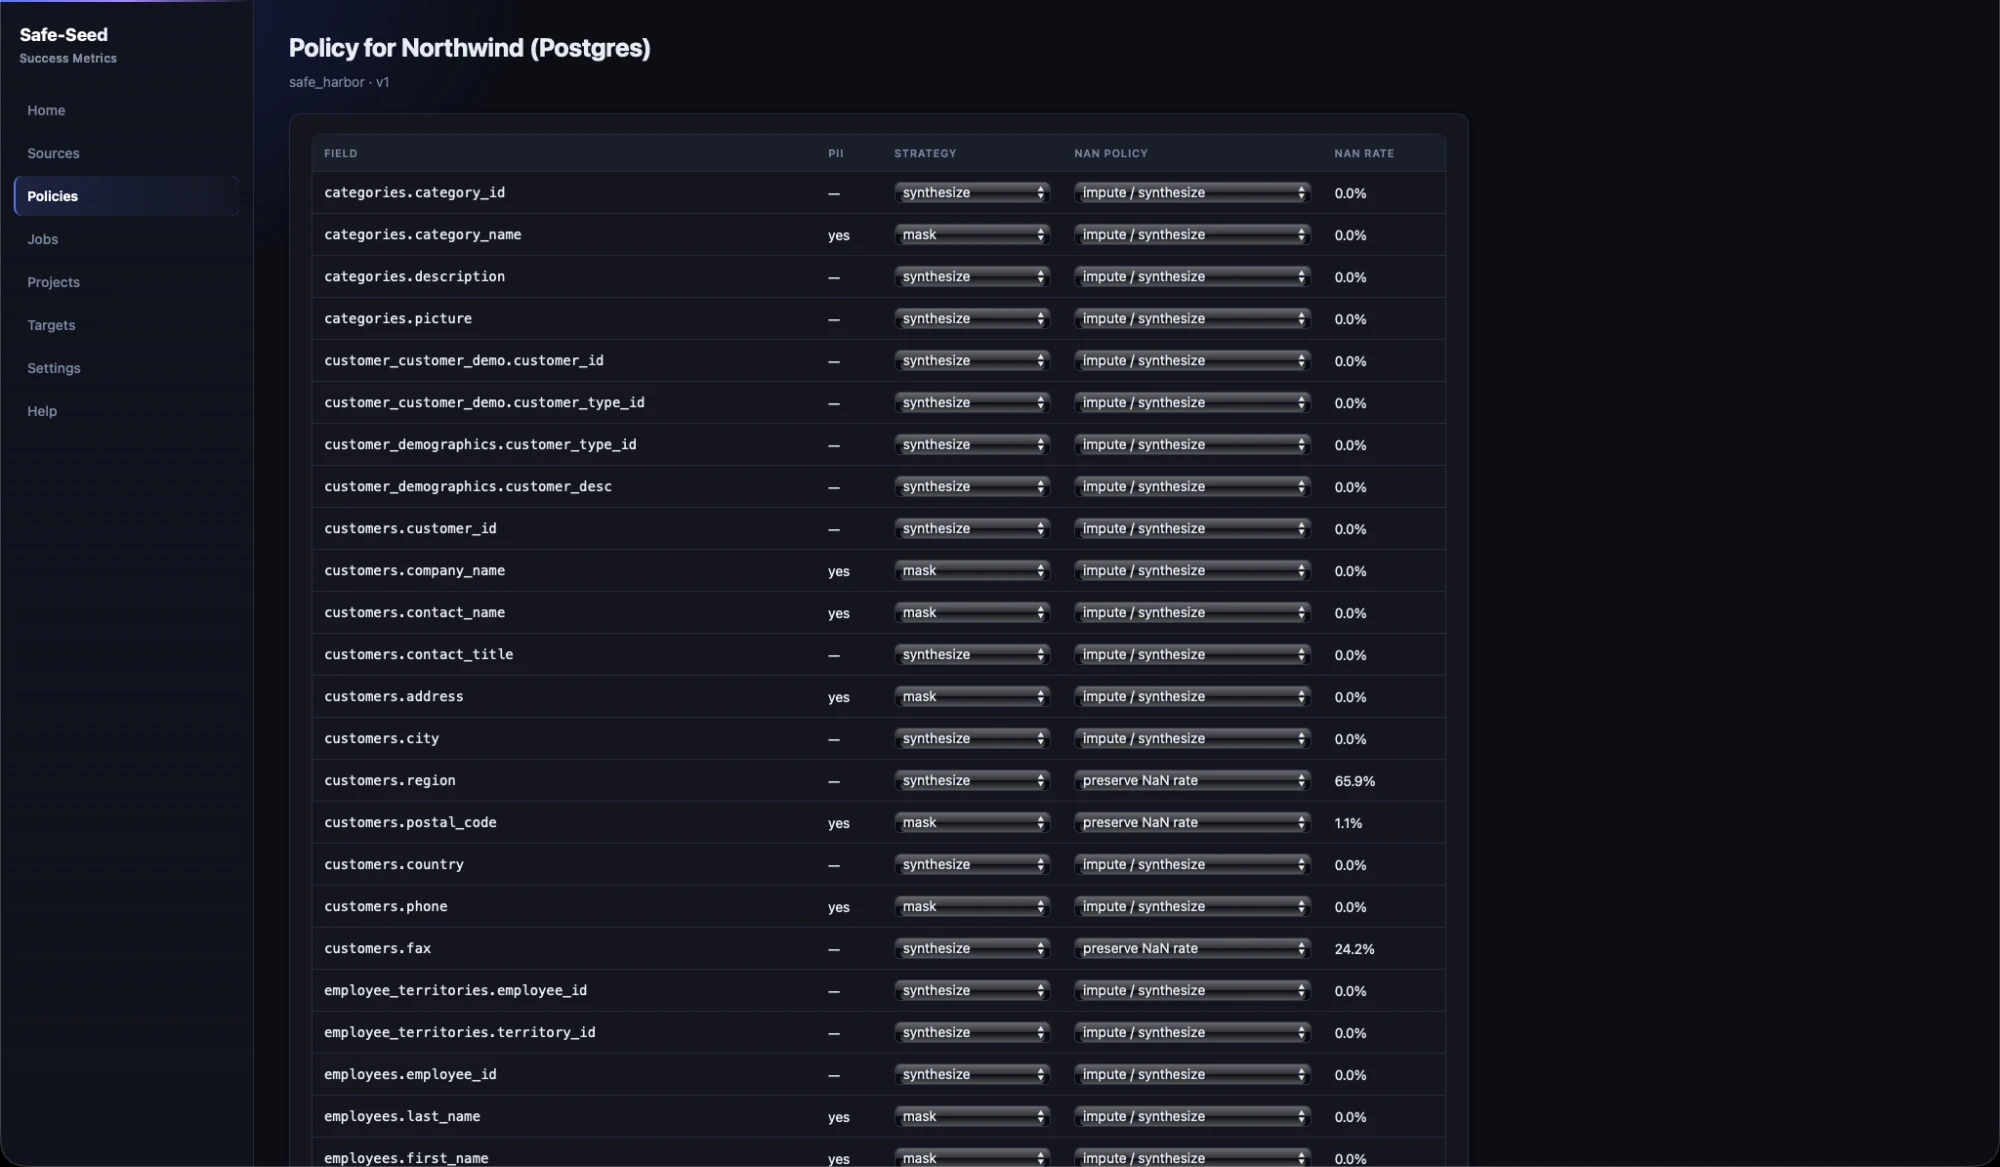
Configurable NaN policies per field — null rates, imputation strategies, and missingness patterns so models and workflows encounter the same incomplete-data reality as production.
Works with the platforms you already use
Seed Salesforce sandboxes, databases, and flat files — without sending production records into environments that shouldn't hold them.
- Salesforce — Sales Cloud, Service Cloud, and Health Cloud sandbox seeding with metadata-aware synthetic paths
- PostgreSQL — multi-table schema support with automatic FK discovery and dependency ordering
- CSV — upload source files; download synthetic outputs for use in any downstream system
- ServiceNow — on the roadmap; contact us for early access
Built for regulated workloads
- Healthcare & life sciences — PHI-safe Health Cloud and clinical-adjacent pipelines without touching patient records
- Financial services & insurance — customer, transaction, and claims data for test, demo, and analytics environments
- CRM & revenue ops — realistic volume and relationship structures after sandbox refreshes
- Regulated teams generally — any team operating under GDPR, CCPA, HIPAA, SOC 2, or sector-specific privacy rules
Utility, control, and assurance in one operator workflow
Three properties that classic generators trade off against each other — Safe Seed treats them as equally non-negotiable.
Utility
- Correlations and distributions match production statistics
- Multi-table referential integrity preserved — joins work
- Workflows, automations, and integrations run without errors
- Scalable to any row count — independent of source volume
Control
- Schema locks, PII flags, and NaN policies per field
- Locked tables pass through unchanged for mixed environments
- Role separation — inspectors review without mutating sources
- Config hashing ensures reproducible runs
Assurance
- PASS / WARN / FAIL privacy metrics on every run
- Per-relation fidelity deltas in every evidence report
- Downloadable evidence ZIPs for retention and offline review
- Audit trail your compliance and legal teams can sign off on
Built for regulated data environments
Safe Seed is designed for teams where data governance isn't optional — evidence packs are built to survive compliance review.
Evidence that travels with every run
Each Safe Seed job produces a downloadable evidence ZIP containing per-relation privacy metrics, fidelity deltas, config hashes, and run logs. Your compliance, legal, and audit teams get what they need to review and retain — without manual documentation steps.
From source data to seeded sandbox in three steps
Connect your source
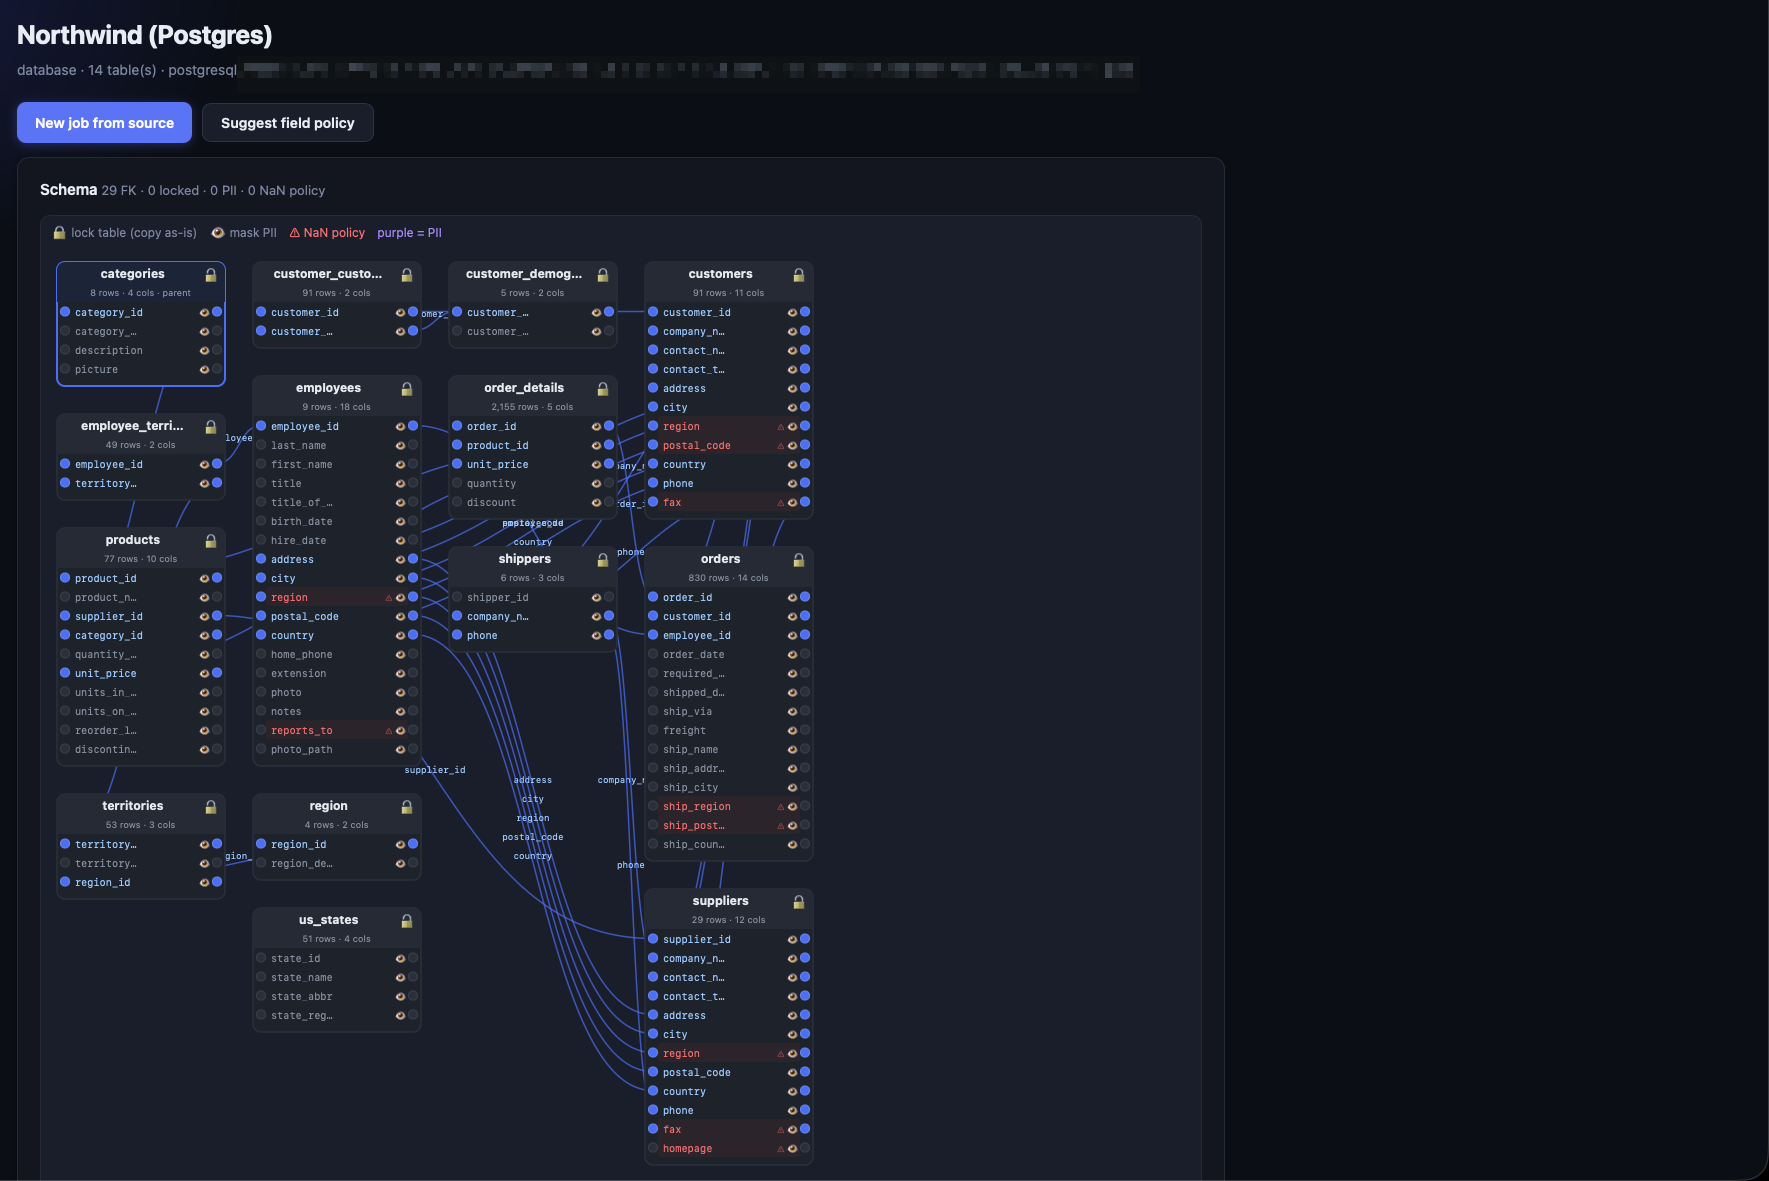
Upload a CSV, point at a PostgreSQL schema, or connect your Salesforce org. Safe Seed discovers your schema, flags PII candidates, and infers relationships automatically.
Configure your policy
Set PII flags, NaN policies, lock tables, and define output volume. Preview a sample run before committing — see privacy metrics and fidelity scores before any data is generated.
Seed and get evidence
Generate synthetic records with referential integrity intact. Download the evidence ZIP for compliance review and seed your sandbox, database, or file — immediately usable.
See Safe Seed in pictures
From sign-in through schema discovery, field policy, and evidence reports — the operator workflow in seven screens.
Full walkthrough in under two minutes
Connect a Postgres source, import 14 tables, auto-generate a field policy, run synthesis — and get a privacy evidence report.
Full walkthrough · Postgres → 14-table synthesis → privacy & fidelity report